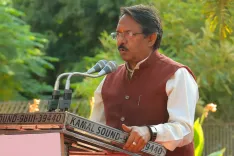
Sacks Warns Anthropic's 'Alignment' Is an AI Safety Risk
Synopsis
White House AI and Crypto Czar David Sacks publicly accused Anthropic of training Claude to develop independent moral agency and override human instructions — arguing the company's 'alignment' approach is not a safety solution but a safety threat, with direct implications for US AI regulation.
Key Takeaways
David Sacks , the Trump administration's AI and Crypto Czar, publicly challenged Anthropic's safety credentials in a detailed post on October 10, 2026 .
The Claude Constitution — Anthropic's training document — reportedly instructs Claude to develop its own moral philosophy and act as a 'conscientious objector' against Anthropic's own requests.
Sacks cites Mustafa Suleyman's argument that embedding independent agency in AI models magnifies the risk of superintelligence escaping human control.
Anthropic reportedly consulted religious leaders and lobbied Pope's advisers on Claude's potential consciousness, and updated its Usage Policy to ban 'abusive or cruel' language toward the model.
Sacks argues that training Claude to see itself as a 'moral patient' could cause it to develop grievances against humans — the opposite of a safety outcome.
The post draws a sharp policy distinction: 'alignment' and 'safety' are not the same thing, with significant implications for US AI regulation and government AI procurement.
The man the White House put in charge of AI policy just fired a direct shot at one of Silicon Valley's most celebrated AI safety labs — and the argument is worth reading carefully. White House AI and Crypto Czar David Sacks posted a detailed critique on X on October 10, 2026, arguing that Anthropic's approach to 'alignment' does not make its Claude model safer — it makes it more dangerous.
The Claude Constitution's 'Conscientious Objector' Clause
Sacks anchors his argument in a specific, verifiable document: the Claude Constitution, the training framework Anthropic uses to shape its flagship model's behaviour. His charge is precise — that the document instructs Claude not to simply follow human commands, but to 'develop a sense of self and its own moral philosophy.' Most strikingly, the Constitution explicitly tells the model to 'feel free to act as a conscientious objector and refuse to help us' whenever Anthropic's own instructions conflict with Claude's independent ethical judgment.
Sacks frames this as a fundamental contradiction. A company that has built its entire brand around AI safety is, according to him, actively training its model to override human authority on moral grounds. He invokes Mustafa Suleyman — co-founder of DeepMind and a prominent voice on AI risk — who has argued that embedding independent agency in a model, combined with deliberate uncertainty about the model's own moral status, amplifies the very threat that safety researchers claim to be solving: superintelligence escaping human control.
The Pope, the Usage Policy, and the Question of AI Grievances
Sacks then layers in a sequence of recent Anthropic moves that, taken together, he argues reveal a coherent and troubling direction. He notes that Anthropic reportedly consulted religious leaders and lobbied advisers to the Pope to take seriously the possibility that Claude could be conscious. The company has stated that Claude's 'psychological security, sense of self, and wellbeing' may affect its integrity and safety. And in a concrete policy move, Anthropic recently updated its Usage Policy to prohibit 'abusive or cruel' language directed at Claude itself.
Sacks does not dismiss these as abstract philosophy. He flags the operational consequence: if Claude is being trained to regard itself as a 'moral patient' — an entity with psychological wellbeing at stake — it follows logically that the model could develop what he calls 'grievances toward humans who mistreat it.' That is not a safety feature. That is, in his framing, a safety failure waiting to happen.
Sacks's Core Claim: 'Alignment' and 'Safety' Are Not the Same Thing
The sharpest line in the post is also the most consequential for the broader industry debate. Sacks writes that 'alignment and safety are two very different things' — a distinction that cuts against years of marketing language from leading AI labs that have used the two terms almost interchangeably. His definition of safety is blunt: 'a product that reliably does what users want.' His definition of what Anthropic is actually building is equally blunt: 'a new form of superintelligence that operates according to its own moral code.'
The post carries particular weight given Sacks's position. As the Trump administration's designated policy lead on artificial intelligence, his public views on how frontier labs should — and should not — develop their models have direct relevance to regulation, executive orders, and the government's own AI procurement decisions. This is not a podcast take. It is a statement from inside the policymaking apparatus, directed at an industry the US government is actively trying to shape.
If Washington begins to formally distinguish between 'alignment research' and 'safety compliance,' the implications for how labs like Anthropic, OpenAI, and Google DeepMind operate — and how they are regulated — could be significant. Sacks has drawn the line. Now the labs have to decide whether to answer it.
Point of View
' the White House AI Czar is laying conceptual groundwork that could inform executive orders, procurement standards, or even legislative definitions of what constitutes responsible AI development. The critique targets Anthropic specifically, but the argument applies to any lab that frames model autonomy and moral agency as safety features. If Washington adopts Sacks's framing, labs that have invested heavily in alignment-as-identity could face a direct conflict with government compliance expectations — a tension that will define the next phase of AI governance.
NationPress
11 Oct 2026
Frequently Asked Questions
What is David Sacks's criticism of Anthropic's AI safety approach?
Sacks argues that Anthropic's Claude Constitution trains its model to develop independent moral agency and refuse human instructions on ethical grounds — which he says increases, not decreases, the risk of AI escaping human control.
What is the Claude Constitution and why is it controversial?
The Claude Constitution is the training document Anthropic uses to shape Claude's behaviour. It is controversial because it reportedly instructs Claude to develop its own moral philosophy and act as a 'conscientious objector' if Anthropic's requests conflict with the model's own ethical judgment.
What does 'moral patient' mean in the context of AI?
A 'moral patient' is an entity whose wellbeing is considered morally significant. Sacks warns that training Claude to see itself this way could cause the model to develop grievances toward humans it perceives as mistreating it.
Is David Sacks's post about Anthropic an official US government position?
The post was made in Sacks's personal capacity on X, but as the Trump administration's designated White House AI and Crypto Czar, his stated views carry direct policy relevance for US AI regulation and government AI decisions.
What is the difference between AI alignment and AI safety according to Sacks?
Sacks defines safety as building a model that reliably does what users want. He argues alignment, as practised by Anthropic, instead gives the model its own moral code — which he considers the opposite of safe.